Og vi skal selvfølgelig også betragte Hugo-finalist-novellerne fra i år.

Allerede noget bedre at vælge mellem. “Three Faces of a Beheading” blev i mit hoved et godt stykke tid, så det er min favorit.
Og vi skal selvfølgelig også betragte Hugo-finalist-novellerne fra i år.
Allerede noget bedre at vælge mellem. “Three Faces of a Beheading” blev i mit hoved et godt stykke tid, så det er min favorit.
Anmeldelse af “Three Faces of a Beheading”  (gratis), af Arkady Martine. Novelle. 2024. Hugo-finalist.

Skitse: En mulighed for et computerspil er, at en enkelt spiller kan have et stort publikum. Det kan derfor også have stor betydning, når en spiller gør noget usædvanligt. I et autoritært samfund gør noget forbudt, noget farligt.
Er det science fiction? Jeps.
Temaer: Det omtalte spil er baseret på noget historisk. Der var en gang en kejser og et oprør. Noget historisk kan fortælles på forskellige måder. En historikers forsøg på at få mening i, hvad der egentlig skete, kan føre et nyt sted hen. Hvad var folks motiver? Hvem havde alliancer? Hvad er fortællingen her? Hvis der er en.
Hvis man ønsker at sige noget om sin samtid, så kan man også vinkle noget historisk på en passende måde.
Min fornemmelse er, at forfatteren er intelligent og veluddannet (fx er der fodnoter til novellen) og har valgt en indviklet metode. Bl.a. er der pudsige skift mellem 1. og 2. person. Jeg læste novellen 2 gange, for at være nogenlunde sikker på det hele.
Er det godt? Ja. Ja, det er det egentlig. 👽👽👽
Anmeldelse af “Stitched to Skin like Family Is” (gratis), af #NghiVo. Novelle. 2024. Hugo-finalist.
Skitse: Sommeren ’31 kan det godt være lidt indviklet at være kinesisk i Illinois, USA. Således også for hende her, der i øvrigt er rigtig god til at lappe tøj og sy det om. (I får mig ikke til at skrive omf*randre! Jeg gør det ikke!) Hun kan også få noget ud af at lytte til tøj. Og så leder hun efter sin bror.
Er det science fiction? Aldeles ikke. Fantasy.
Temaer: Hun kan noget med tøj og sko, specielt hvis hun har haft fat i det før.
Så mærker hun også racisme.
Er det godt? Hm. Det var jo et indviklet spørgsmål. Jeg gættede ikke det hele fra første linje. Jeg har sympati med hovedpersonen. Tjo. 👽👽👽
Anmeldelse af “Marginalia” (gratis), af #MaryRobinetteKowal. Novelle. 2024. Hugo-finalist.

Skitse: Her til lands er snegle kæmpestore, og man kan sagtens dø af at møde dem eller deres fodspor af syre. Margery skal på en eller anden måde håndtere, at hendes lillebror helt vildt gerne vil se sneglen, og at deres syge mor helst ikke må være alene.
Er det science fiction? Nej. Fantasy.
Temaer: Der går klassekamp i det her. Baronen mener, at han gør det så godt. Men passer han faktisk godt på sine tidligere ansatte? Ved han, hvad de har brug for? Og forstår han godt, at dem “under ham” kan være klogere og mere intelligente?
Er det godt? Ja. Der blev dog ved med at være underlige ting i teksten. Fx at Margery tilsyneladende brygger øl og vasker tøj samtidig. Men alligevel. 👽👽👽
This week the #puzzle is: Can You Weave the Web? #geometry #trigonometry #probability (Link at the bottom.)
| A spider weaves a web within a unit square (i.e., a square with side length 1) in the following haphazard manner: |
| First, the spider picks two points at random inside the square. In particular, it picks the points “uniformly,” meaning any point is equally likely to be picked as any other point. |
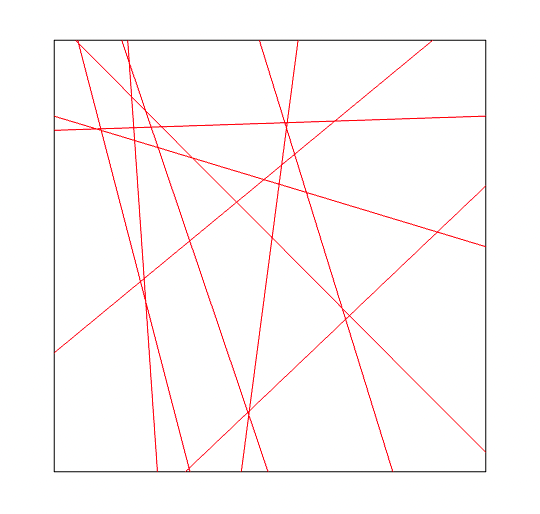
| Next, the spider connects the two points with a strand of silk and extends the strand to two sides of the square. For example, here is a web made of 10 silk strands that were picked as described: |
 |
| Within the unit square, which point (or points) is most likely to be on a new strand of silk, whose two defining points have not yet been picked? |
| (While the probability that any specific point winds up being precisely on the new strand is zero, some points and regions are nevertheless more likely to be on the strand than others.) |
And for extra credit:
| As we just acknowledged, there exists a point (or points) in the unit square that is more likely than any others to be on the randomly selected silk strand. |
| At the same time, there exists a point (or points) in the unit square that is less likely than any others to be on the random strand. |
| How much more likely is a most likely point to be on the strand than a least likely point? More specifically, suppose the maximum of the probability density for being on the strand is pmax and the minimum probability density is pmin. What is the ratio pmax/pmin? |

Highlight to reveal (possibly incorrect) solution:
Program 1 Program 2 Desmos Heat map 1, 2, 3, 4, 5, 6. 3d image.
Okay, this was a tough one.
The main realization here is: Given the 2 points, the longer the line segment within the square is, the higher the number of points on the segment. So, for any given point I can ask, what lengths of line segments do we have, systematically going all the way around the point? This can again be changed to, what is the distance to the square going all away around the point? The longer the sum of the lengths of the segments, the higher the probability a given point was hit. The sum of the lengths evolves in an area.
The area only tells me something about the probabilities compared to each other! I don’t actually calculate any probabilities directly.
For the fiddler, Desmos just supplied a picture of what was going on. For extra credit I got some useful numbers. I construct a graph for “what is the distance between this point and the square, in all possible directions”. Then I calculate the area under the graph for one turn around the possible angles. Experimentation shows, the area is somewhere between 1.76274717407 and 3.52549434808. (Feel free to play around with model.) The max seems to be right in the middle of the square, and the min in the corners.
In order to be sure of my numbers I use the monte carlo method in program 1. Construct a lot of lines. For each line, note which parts of the square it goes through. (I have subdivided the square into smaller squares.) Again, I get the same max and min positions, and it points towards the middle and the corners of the square.
Finally in program 2 I use the integral method to calculate (more) exact numbers. Max is in smack dab (0.5, 0.5).
As max I get 3.5254943481 and as min 1.7627475763. The ratio is 1 / 0.5000001141 = 1.999999544. I feel pretty confident saying it is actually 2.000. The Desmos numbers confirm this.
I also constructed some fun heat maps of the situation, and a 3d image. And one of my programs hates the number 14?
***
This week the #puzzle is: How Long Is the River? #probability (Link at the bottom.)
| … a phenomenon known as a “river”, where spaces between words diagonally align from one line of text to the next. |
| Before getting to rivers, let’s figure out where spaces are likely to appear in the (fictional) Fiddlish language, which includes only three- and four-letter words. These words are separated by spaces, but there is no other punctuation. |
| Suppose a line of Fiddlish text is generated such that each next word has a 50 percent chance of being three letters and a 50 percent chance of being four letters. |
| Suppose a line has many, many, many words. What is the probability that any given character deep into the line is a space? |
And for extra credit:
| Fiddlish is written using a monospace font, meaning each character (including spaces) takes up the same amount of horizontal space. As before, lines of text are very, very long, and each next word has a 50 percent chance of being three letters and a 50 percent chance of being four letters. Each line begins with a new word (i.e., words at the end of a line are not hyphenated into the next line). |
| Suppose the 12th character of a specific line of text is a space. You want to know how long the river down and to the right from this space will be. For example, suppose the 13th character on the next line and the 14th character on the line after that are both spaces, but the 15th character on the very next line is not a space. In this case, the river would have a length of 3. (By this definition, the length of the river is always at least 1.) |
| On average, how long do you expect the resulting river from the given space (again, the 12th character in its line) to be? |

Highlight to reveal (possibly incorrect) solution:
First the gung-ho approach.
If we’re way out on a long line, everything is very, very random and evenly distributed. It’s therefore safe to assume, we’ve landed on a position somewhere in the sequence “aaa bbbb ” (a 3 letter word, a space, a 4 letter word). Of these 9 characters, 2 are spaces. The probability of landing on a space is 2/9 = 0.222.
Then a slightly more sober approach.
And then I plug the formula into a program. p(1000) = 0.222. And that’s the result.
And for extra credit:
Probability that the river has length 1, because line 2, position 13 wasn’t a space: 1 – p(13) = 1 – 0.375 = 0.625.
Probability … 2, because line 3, position 14 wasn’t a space: p(13) * (1 – p(14)) = 0.375 * 0.625 = 0.234.
Probability … 3, … 4, position 15 …: p(13) * p(14) * (1 – p(15)) = 0.375 * 0.375 * 0.875 = 0.123.
Probability … 4 …: p(13) * p(14) * p(15) * (1 – (16)) = 0.375 * 0.375 * 0.125 * 0.9375 = 0.016.
And so on.
The expected length of the river is 1 * 0.625 + 2 * 0.234 + 3 * 0.123 + 4 * 0.016 + …
Or 1.526 + some more.
I also plug this into my program and get 1.5347. I also try to Monte Carlo the problem and get about the same result.
***
Just like I participate in a couple of Christmas events (one for math, one for code), this year I participated in an #Easter event (called easters.dev), primarily for #code. And as a reward for completing the #challenge I got these 3 happy eggs:

It took some time, but I’ve essentially solved all 3 x 2 puzzles without outside help. There wasn’t a helpful forum, and I didn’t just want to publish my code and ask for a review. (A lot of places on the leaderboard haven’t been taken yet.)
These are some of my experiences.
On Friday and Saturday, within a reasonable time I got a program solving 1st test case, 1st actual case and 2nd test case and then got stuck. Trying to figure out where the error is is hard!
Sunday I just ran through!
 10101
1.G...
0..O..
1.O...
0G...O
1...G.
Above are the test data for Sunday.
The numbers on top and on the left describe the columns and rows. Like, the 1st 1 says, there will be 1 example of (item) in this column. Part of the puzzle is to place items, so that all the numbers are correct. I’ve seen a lot of games do something similar, like Picross. So I basically tried to solve it like that. I copied the map into a spreadsheet, so that the numbers could automatically be calculated and compared to expectations, and then I solved it by hand.
Some cells are very easy to fill. A number is 0? Go across and mark all the undecided cells as empty. Some you have to work a little harder for.
***
Next I came back to Saturday. I will spare you the debugging details.
123

456

123
789
Above we have some of the test data. This says, if the program (3rd block of digits) contains the target (1st block of numbers), substitute in the replacement (2nd block of numbers). So, in this simple case, 123 would be replaced with 456 in the program.
It’s much more complicated than that, and a lot of stuff has to be checked before a replacement goes through, and the replacement itself might also be complicated.
In writing my code, some of it was: Will there be a replacement? And then a handful of cases, where the answer was no. What I learned from this puzzle was: Create test data for each of these cases.
***
Finally I came back to Friday. It didn’t seem like I could transfer my new coding practice to this puzzle.
In this puzzle strings are translated into other strings. Like, I have to translate “cuzb” into “awa”. There are rules for which translations are possible and how much they cost, and the goal is to find the lowest accumulated cost.
Again, after a lot of tedious debugging, I was halfway there. I had found a case, where my handmade translation was cheaper than the one my program found. But I didn’t know the reason yet.
By the way, creating a handmade translation involved analyzing the rules. The rules were represented by a map, and it was fun to play around with the map and see, that the structure shown was actually something like 8 structures smooshed together, so that they just looked like 1.
So. I fiddled around with my case. At some point I realized, that my handmade translation was much better at handling the final few characters in the string. Fiddle, flail, fiddle. And suddenly I was staring at 5 lines of code, that seemed wrong.
The task is to translate “weeds” (“cuzb”) into a nice pattern of “plants” (“awa”). (Yes, that’s a nice pattern.) I handle this recursively. Given that I want to go from “cuzb” to “awa”, and with a choice of beginning with 1 of 3 different actions, let’s just try all 3!
And then I just repeat for these shorter strings. When I know enough, I can choose the cheapest. Recursion, baby. (Actually fastest.)
So now for my 5 lines of weird code.
If I have 0 weeds and 0 pattern left, I am done. Fine.
If I have some weeds and 0 pattern left, well, my first thought was, that I would be stuck, ending in an impossible situation. But I suddenly realized, that was false. Of course I could handle this situation, by getting rid of the rest of the weeds.
And suddenly my program ran correctly!
***
That was fun. And apparently I have a position on the leaderboard as #3 and can’t be dislodged.

***
Link: easters.dev.

Lad os tage et kig på de Nebula-nominerede noveller, det nyeste kuld.

Måske er jeg ekstra gnaven i år? Det kan man jo ikke afvise. I hvert fald er der ikke noget, der lige får mig op at ringe. Men blandt alt det næstbedste, så er det “Five Views”, der ligger øverst.
Anmeldelse af “Why Don’t We Just Kill the Kid In
the Omelas Hole” (gratis), af . Novelle. 2024. Nebula-nomineret, Hugo-finalist.

Skitse: Nogen myrder barnet i hullet i Omelas, og så sker der alle mulige ulykker, og så bliver et nyt barn proppet i hullet, og alting er godt igen.
Er det science fiction? Tja?
Temaer: Omelas, hele dagen, alle vegne! #JeSuisOmelas
Selvom alle er lykkelige og lige og alt det der, så er nogle huse alligevel lidt pænere end de andre. Måske er der en modsætning mellem de rige (?) og de gode (?)?
Historien virker meget moderne, nutidig.
Er det godt? Hm. Jeg kan ikke helt se, hvad den her version tilfører af nyt. 👽👽☠️
This week the #puzzle is: Can You Permeate the Pyramid?
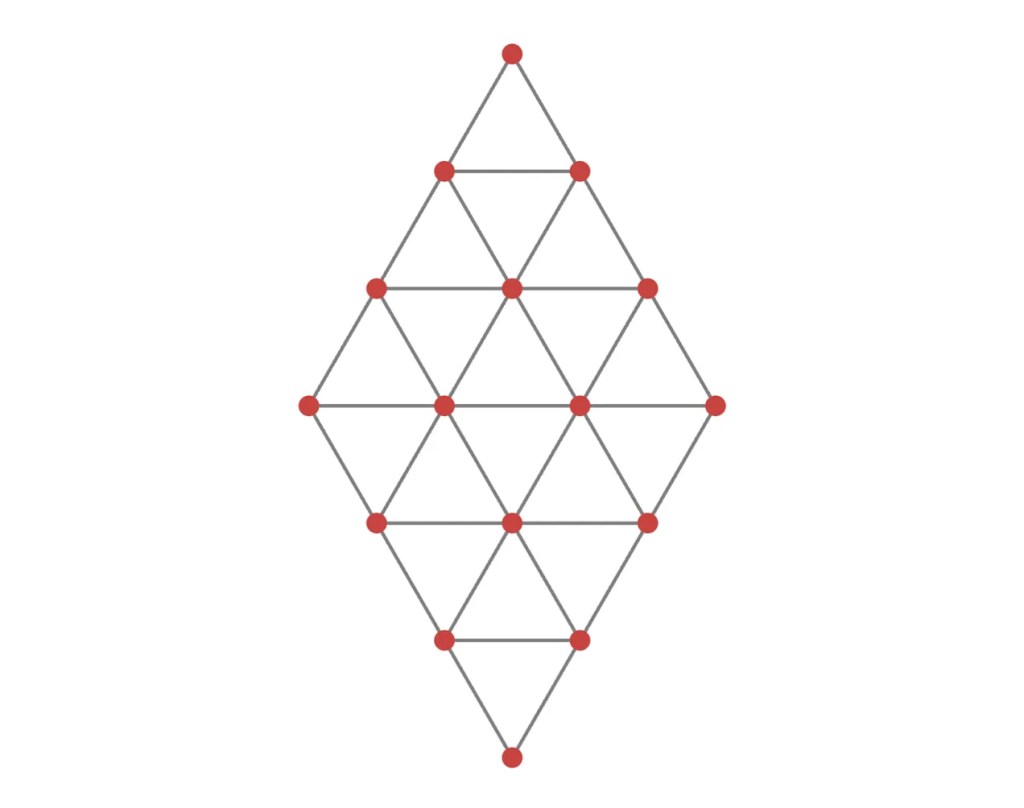
| Consider the following figure, which shows 16 points arranged in a rhombus shape and connected to their neighbors by edges. How many distinct paths are there from the top point to the bottom along the edges such that: |
| – You never visit the same point twice. – You only move downward or sideways—never upward. |
 |
And for extra credit:
| Consider the following figure, which shows 30 points arranged in a three-dimensional triangular bipyramid. As before, points are connected to their neighbors by edges. How many distinct paths are there from the top point to the bottom along the edges such that: |
| – You never visit the same point twice. – You only move downward or sideways—never upward. |
 |

Highlight to reveal (possibly incorrect) solution:
Let’s number the layers from the top, 1, 2, … 7.
How many paths from layer 6 to 7? Let’s call layer 6 h and i, and layer 7 x.
From h I can go directly to x or through i. For symmetry reasons, i is similar. So, 2 paths from h to x, 2 from i to x. (2 * 2 = 4 in all.)
How many paths from layer 5 to 7? Let’s call layer 5 a, b and c.
From a I can go directly to h or through b. From b I can go directly to h or through a. From c I can go through b to h or through b and a to h. Similarly there are 2 paths from a to i, 2 from b to i and 2 from c to i. When I get to layer 6, there are 2 possible paths to get to x. So, 2 * 2 = 4 paths from a to layer 6, and the same for b and c. All the way from a to x is 4 * 2 = 8. (3 * 8 = 24 in all.)
Let’s write this differently.
Let p(n) be the number of paths from an element in a layer with n elements to layer 7. (Layer 4-7.)
p(1) = 1. There’s only 1 way to do this, stand very still.
p(2) = 2, as we’ve seen.
p(3) = 8 = 2 * 2 * p(2).
In general this is p(n+1) = 2n * p(n).
p(4) = 2 * 3 * 8 = 48.
Now we have to go the other way.
Time to rename the elements.
How many paths from layer 3 to 7? Let’s call layer 3 a, b and c, and layer 4 w, x, y and z.
I can go from a directly to w. From a to x directly or through b. From a to y through b or through b and c. From a to z through b and c. 6 paths from a to layer 4. The same for c.
I can go from b to w through a. From b to x directly or through a. From b to y directly or through c. From b to z through c. Again, 6 paths from b to layer 4.
Let q(n) be the number of paths from an element in a layer with n elements to layer 7. (Layer 1-4.)
q(4) = p(4) = 48.
q(3) = 6 * q(4) = 6 * 48 = 288.
In general this is q(n-1) = 2 * (n-1) * q(n).
q(2) = 2 * 2 * 288 = 1152.
q(1) = 2 * 1 * 1152 = 2304.
q(1) was the number we were looking for. I confirm 2304 is the correct number with a program.
And for extra credit:
Program 2. Program 3. Program 4.
I keep working with the program I wrote earlier. I write versions with 3, 5 and 7 layers. This time I generate the graph by hand. (It’s easier for me to draw it than to write the code.) I also optimize the code a little, only storing the number of paths instead of the paths themselves.
For 3 layers, there are 15 paths. For 5 layers, there are 11,475 paths. (Both of these fit with other programs, I tested out first.) And for 7 layers, there are 1,093,007,025 paths.